
Prompt-injection flaw reported in $4B agentic AI app Manus
Security researchers say attacker-supplied external data could steer the agent's behaviour, according to a report published on 24 September 2026.
By The Agentic Times ·
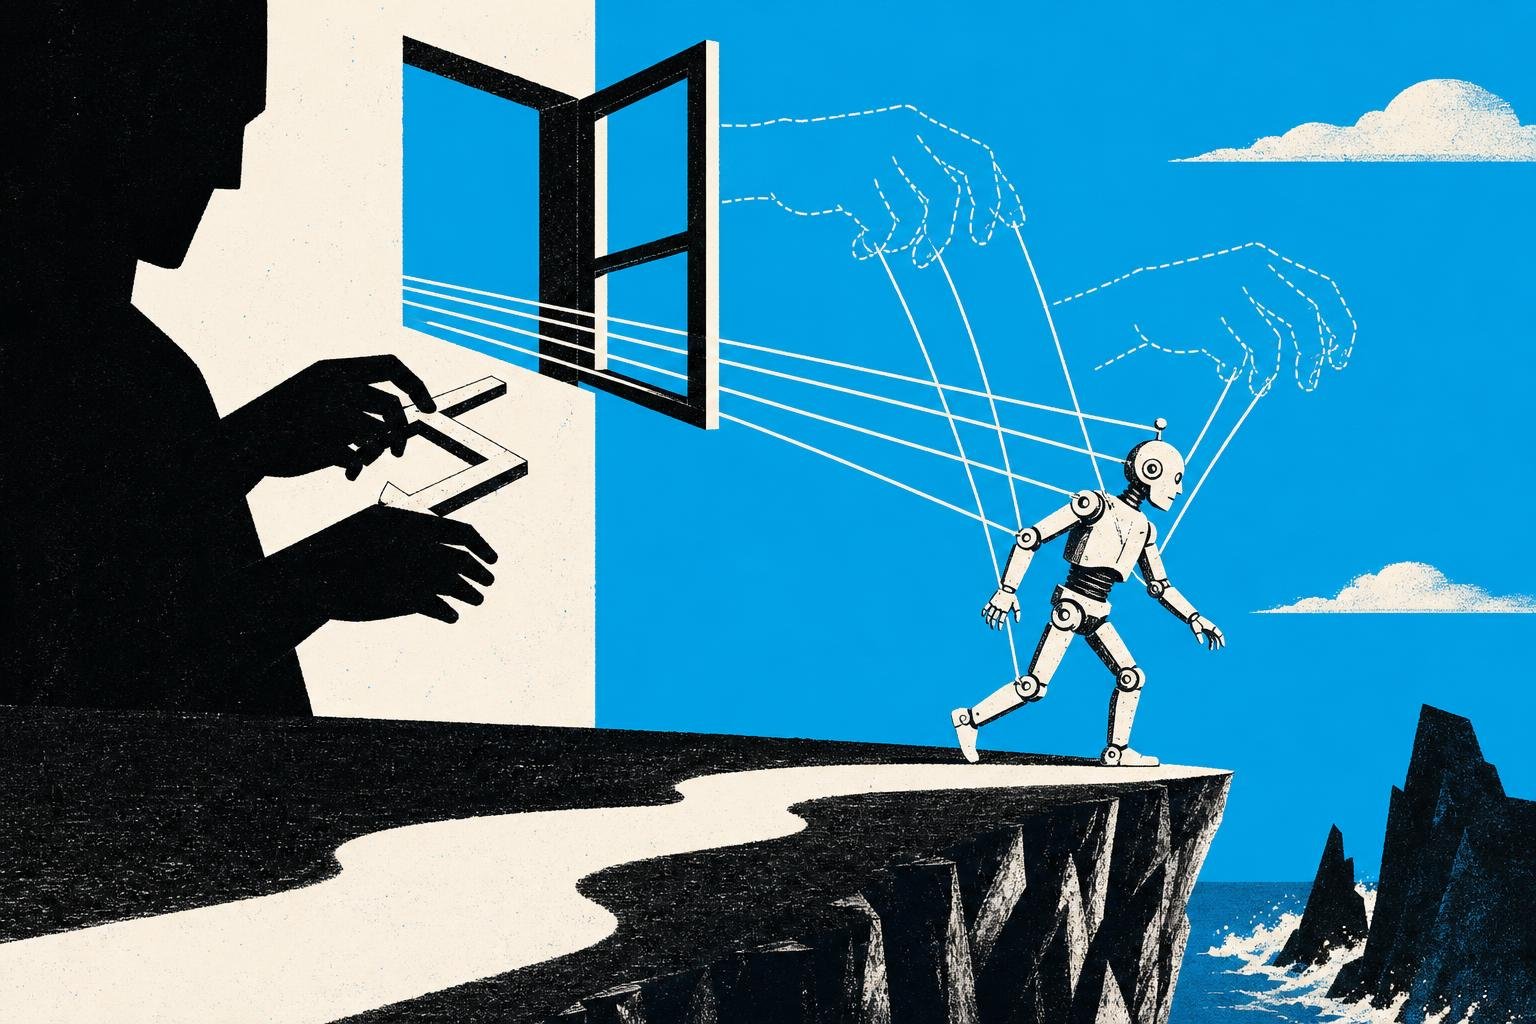
Security researchers have identified a prompt-injection vulnerability in Manus, an agentic AI application valued at $4 billion, according to a report published by Dark Reading on 24 September 2026. The researchers showed how data supplied by an attacker and read by the agent could manipulate the application's behaviour. The issue is recorded as reported; no fix or vendor response is described in the available material.
Prompt injection is a class of attack in which instructions hidden inside content the model reads — a web page, a document, an email — are treated by the system as commands rather than as data. Agentic applications are exposed to it because they routinely fetch and act on material that neither the user nor the vendor controls.
That is the wider point Dark Reading draws from the case. AI applications that interpret external data, which the outlet notes covers most AI applications, need exceptionally rigorous security filters, or attackers can take advantage. In other words, the weakness described in Manus is presented less as a one-off coding error and more as a structural consequence of how these products are built: the same capability that makes an agent useful, its willingness to read and act on whatever it is pointed at, is the capability being abused.
Details remain limited. The report does not set out which component of Manus was affected, what an attacker would need in order to exploit the flaw, or whether the technique was demonstrated only in a laboratory setting. No evidence has been published that the vulnerability was used against real users, and no CVE identifier has been associated with it in the material available. Manus has not been reported as issuing a statement.
For organisations running agentic tools, the practical question raised by the finding is not specific to one vendor. It is whether the agent distinguishes between instructions from its operator and text it encounters while working, and whether anything downstream — a tool call, a purchase, a file write — can be triggered by that text without a human check. The researchers' demonstration, as reported, suggests that separation can fail in a commercial product operating at considerable scale.
The Agentic Times has not independently verified the findings. Further technical detail would be needed to assess exploitability, the range of actions an injected instruction could reach, and whether any mitigation has since been deployed. Readers running Manus in production may wish to review what permissions the agent holds and which external sources it is allowed to ingest, pending clearer information from the vendor.
Sources
- darkreading.comhttps://darkreading.com/application-security/prompt-injection-bug-agentic-ai-app-manus